Otto-Wasserstein and Fisher-Rao Gradient flows for inference: Gaussian restriction and local-linear approximation
Overview
Abstract
A modern perspective in machine learning and statistics is to frame computation as optimizing the relative entropy. For example, researchers have exploited the Otto-Wasserstein gradient flow of the Kullback--Leibler (KL) divergence for machine learning and statistics. In this talk, I will first show the analysis of the Gaussian variational inference application of the Hellinger-Kantorovich (HK, a.k.a. Wasserstein-Fisher-Rao) gradient flows. If time, I will then showcase a local-linear approximation of the Otto-Wasserstein gradient flow of the inclusive KL divergence.
Presenters
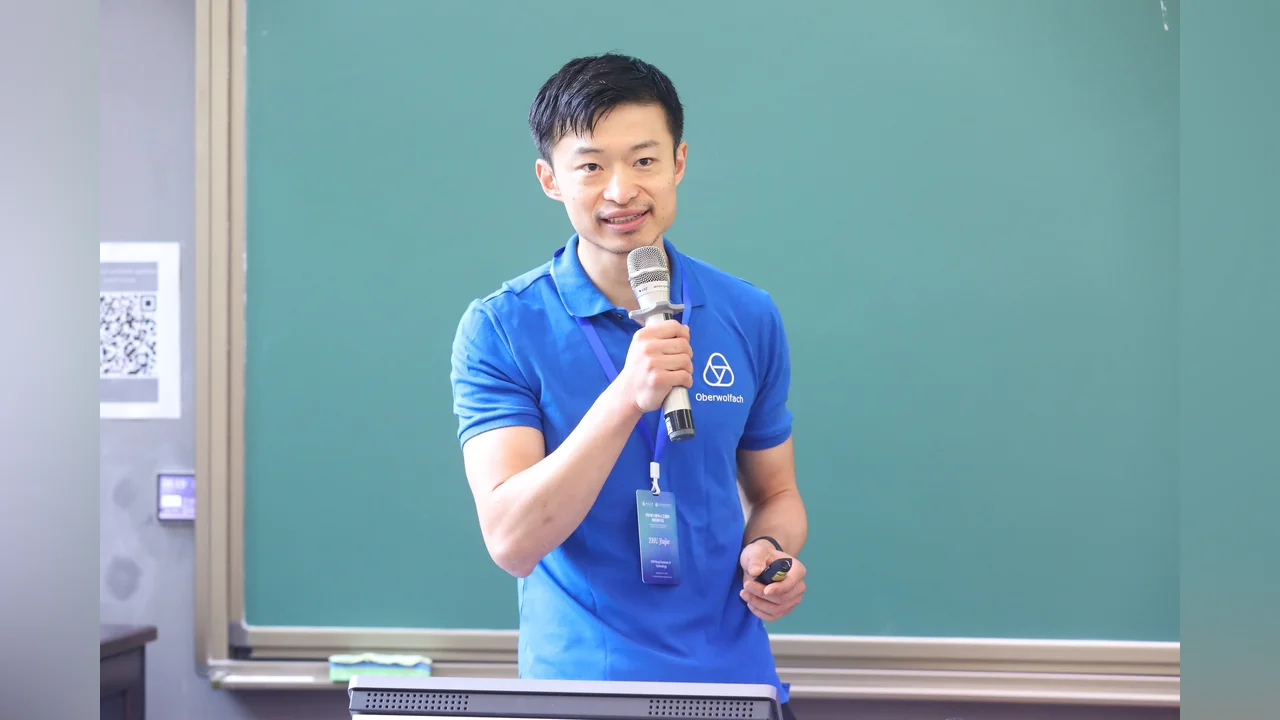
Prof. Jia-Jie Zhu, KTH Royal Institute of Technology, Stockholm, Sweden.
Brief Biography
Jia-Jie Zhu (https://jj-zhu.github.io/) is an applied mathematician and associate professor in mathematics at the KTH Royal Institute of Technology in Stockholm, Sweden. He received Ph.D. training in optimization, at the University of Florida, USA and a B.Sc. degree in mathematics from Fudan University, China. He is interested in the intersection of machine learning, optimization, and analysis (PDE), on topics such as gradient flows of probability measures, optimal transport, and numerical optimization.